Mohamed Abdelfattah · Launch Video Breakdown: Hook, Pacing & Motion Design
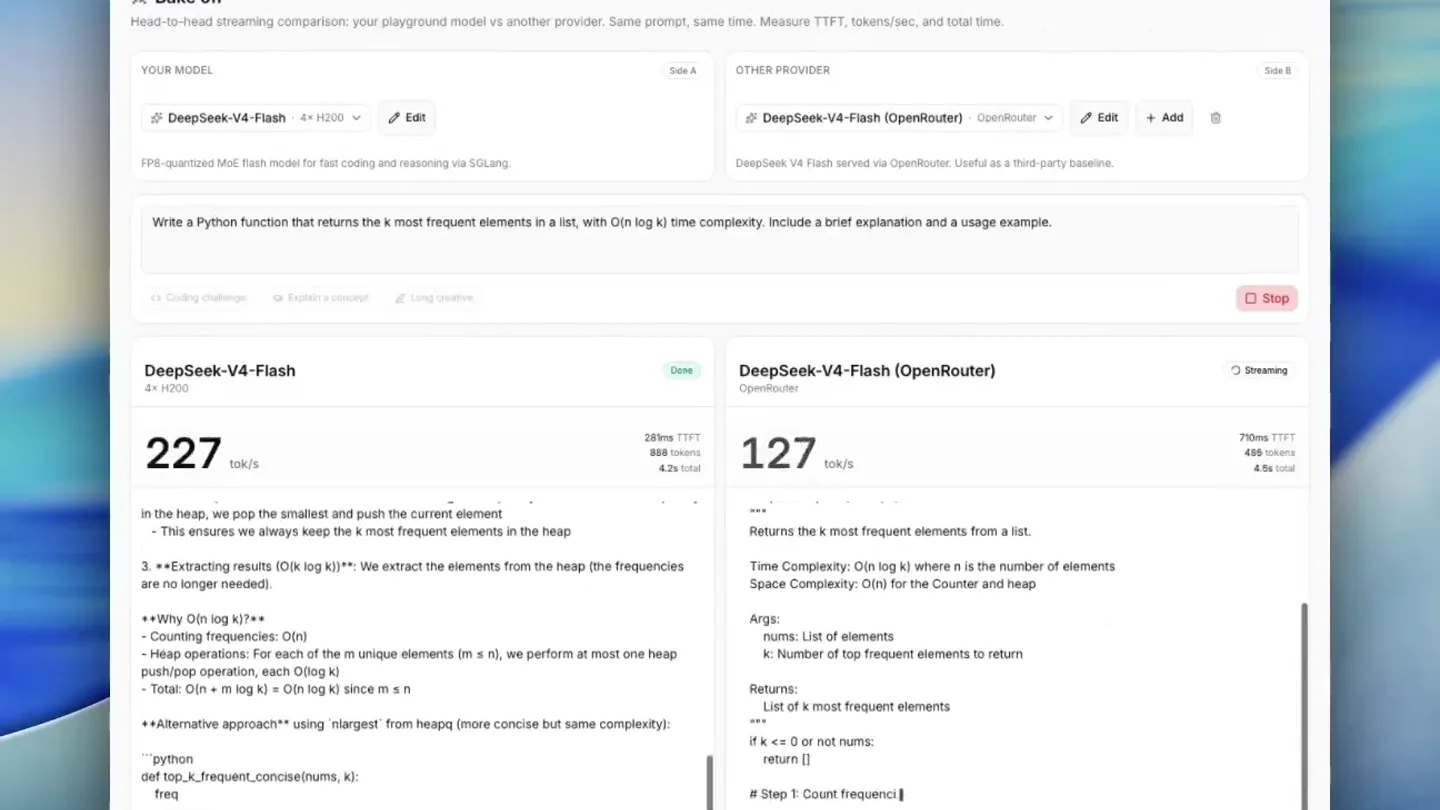
DeepSeek V4 Flash, the top model on @OpenRouter, gets about 80 tok/s on their platform. On @makora_ai, you can get 200 tok/s. We’ve officially launched our own inference endpoints, and our mission to maximize performance is just getting started. See for yourself in the recording https://t.co/o1zJ3eMvHv
Scene-by-scene timeline & spoken transcript
The Hook
Performance Benchmark Introduction
“(No spoken dialogue — ambient visual of a web application interface.)”
- On screen
- Home > Bakeoff Bake off Head-to-head streaming comparison: your playground model vs another provider. Same prompt, same time. Measure TTFT, tokens/sec, and total time. YOUR MODEL DeepSeek-V4-Flash 4x H200 Edit FP8-quantized MoE Flash model for fast coding and reasoning via SGLang. OTHER PROVIDER DeepSeek-V4-Flash (OpenRouter) Edit + Add DeepSeek V4 Flash served via OpenRouter. Useful as a third-party baseline. Write a Python function that returns the k most frequent elements in a list, with O(n log k) time complexity. Include a brief explanation and a usage example. Coding challenge Explain a concept Long creative Stop DeepSeek-V4-Flash 4x H200 Streaming 218 tok/s 289ms TTFT 96% total 1.0s total Here's a Python function that returns the k most frequent elements from a list. python import heap DeepSeek-V4-Flash (OpenRouter) OpenRouter Streaming 120 tok/s 790ms TTFT 44% total 1.0s total
- Camera
- Static, wide shot of a web application interface, centered.
- Motion
- Text streaming animation, numerical counters incrementing, progress bar filling.
Problem Agitation
Performance Disparity Highlight
“(No spoken dialogue — ambient visual of a web application interface.)”
- On screen
- Home > Bakeoff Bake off Head-to-head streaming comparison: your playground model vs another provider. Same prompt, same time. Measure TTFT, tokens/sec, and total time. YOUR MODEL DeepSeek-V4-Flash 4x H200 Edit FP8-quantized MoE Flash model for fast coding and reasoning via SGLang. OTHER PROVIDER DeepSeek-V4-Flash (OpenRouter) Edit + Add DeepSeek V4 Flash served via OpenRouter. Useful as a third-party baseline. Write a Python function that returns the k most frequent elements in a list, with O(n log k) time complexity. Include a brief explanation and a usage example. Coding challenge Explain a concept Long creative Reset Run bake off DeepSeek-V4-Flash 4x H200 Done 227 tok/s 289ms TTFT 96% total 4.2s total 3. **Extracting results (O(k log k))**: We extract the elements from the heap (the frequencies are no longer needed): - Why O(k log k)? - Counting frequencies: O(n) - Heap operations: For each of the m unique elements (m ≤ n), we perform at most one heap push/pop operation, each O(log k). - Total: O(n + m log k). O(n log k) since m ≤ n. **Alternative approach** using `nlargest` from `heapq` (more concise but same complexity): python def top_k_frequent_concise(nums, k): freq_map = Counter(nums) return [element for element, _ in heapq.nlargest(k, freq_map.items(), key=lambda x: x[1])] WINNER DeepSeek-V4-Flash DeepSeek-V4-Flash (OpenRouter) OpenRouter Done 139 tok/s 790ms TTFT 44% total 4.2s total 2. **Maintaining a min-heap of size k (O(n log k))**: - We iterate through each unique element and its frequency. - We push (frequency, element) into a min-heap. - If the heap exceeds size k, we pop the element with the smallest frequency. - This ensures the heap always contains the k elements with the highest frequencies. 3. **Extracting results (O(k log k))**: We sort the heap in descending order by frequency and extract just the elements. **Why O(k log k)?** - The `Counter` creation is O(n). - Each heap operation (push/pop) is O(log k), and we perform at most n operations. - The final sort is O(k log k), but since k ≤ n, this doesn't affect the overall complexity. This 1.64x
- Camera
- Static, wide shot of a web application interface, centered.
- Motion
- Text streaming animation, numerical counters incrementing, progress bar filling, 'WINNER' badge reveal, 'X' multiplier reveal.
Product Reveal
Technical Deep Dive & Superiority
“(No spoken dialogue — ambient visual of a web application interface.)”
- On screen
- Home > Bakeoff Bake off Head-to-head streaming comparison: your playground model vs another provider. Same prompt, same time. Measure TTFT, tokens/sec, and total time. YOUR MODEL DeepSeek-V4-Flash 4x H200 Edit FP8-quantized MoE Flash model for fast coding and reasoning via SGLang. OTHER PROVIDER DeepSeek-V4-Flash (OpenRouter) Edit + Add DeepSeek V4 Flash served via OpenRouter. Useful as a third-party baseline. Explain how KV-cache works in transformer inference, and why it matters for serving throughput. Keep it under 200 words. Coding challenge Explain a concept Long creative Stop DeepSeek-V4-Flash 4x H200 Streaming 239 tok/s 279ms TTFT 96% total 1.2s total During transformer inference, each new token requires attention over all previous tokens. Without optimization, the model recomputes the Key (K) and Value (V) matrices for every prior token at each step—huge waste. **KV-cache** solves this by storing the K and V vectors from previous tokens in memory. For each new token, the model only computes its own K and V, then retrieves the cached ones. This reduces per-step computation from O(N) to O(1) for the attention mechanism. **Why it matters for throughput?** By avoiding redundant computation, KV-cache dramatically speeds up generation (lower latency per token). Moreover, the cache grows linearly with sequence length and batch size, consuming significant GPU memory. This memory bottleneck limits how many concurrent requests a server can handle (batch size) and how long sequences can be. Efficient KV-cache management (e.g., PageAttention, quantization) is therefore critical for maximizing serving throughput. DeepSeek-V4-Flash (OpenRouter) OpenRouter Streaming 110 tok/s 836ms TTFT 44% total 1.2s total During transformer inference, each new token's generation requires computing attention over all previous tokens. Without optimization, the model recalculates the Key (K) and Value (V) matrices for every prior token from scratch at each step—extremely redundant. **KV-cache** stores the K and V tensors from previous decoding steps in GPU memory. For each new token, the model computes only its new K and V, appends them to the cache, and then performs attention over all cached sequences. This reduces per-token computation from O(seq_len^2) to O(1) for the cached layers, dramatically accelerating generation (time-to-first- token and inter-token latency). **Why it matters for throughput?** KV-cache reduces compute per token, allowing higher batch sizes on the same hardware. This directly increases tokens-per-second served (throughput). However, the cache is memory intensive (scales linearly with batch size x seq_len x layers). Efficient management (e.g., vLLM's PagedAttention) is vital to avoid memory fragmentation, enabling more concurrent requests without OOM errors. Reset Run bake off Done Done WINNER DeepSeek-V4-Flash 2.48x
- Camera
- Static, wide shot of a web application interface, centered.
- Motion
- Text streaming animation, numerical counters incrementing, progress bar filling, 'WINNER' badge reveal, 'X' multiplier reveal.
Call to Action
Creative Application & Final Performance
“(No spoken dialogue — ambient visual of a web application interface.)”
- On screen
- Home > Bakeoff Bake off Head-to-head streaming comparison: your playground model vs another provider. Same prompt, same time. Measure TTFT, tokens/sec, and total time. YOUR MODEL DeepSeek-V4-Flash 4x H200 Edit FP8-quantized MoE Flash model for fast coding and reasoning via SGLang. OTHER PROVIDER DeepSeek-V4-Flash (OpenRouter) Edit + Add DeepSeek V4 Flash served via OpenRouter. Useful as a third-party baseline. Write me a very long poem about a shark that likes to optimize GPUs Coding challenge Explain a concept Long creative Stop DeepSeek-V4-Flash 4x H200 Streaming 183 tok/s 190ms TTFT 96% total 5.7s total A chaotic, beautiful, untamed sea, He spans computing's vast hierarchy. Of light and logic, a liquid mystery. He re-ordered it, a fractal art, A path for every photon's depart. Through silicon canyons, shadows gained a grace, A perfect, rendered, digital space. He felt the power, not of tooth or claw, But of a perfectly optimized law. He did not hoard this knowledge for his own, He was a trail, a call, a silent tone, A pattern for all that's yet to be, For any other mind that came to play A ghost in the machine, a silent guide, With a great white smile, open wide. He was DeepSeek-V4-Flash (OpenRouter) OpenRouter Streaming 101 tok/s 560ms TTFT 44% total 5.7s total "You see a hunk of rust, a lifeless case. I see a future, where time has no trace. I see a when where every single byte Is a perfect, tiny, shining, solar light. I see the shader of a coral fan, A million polygons, a perfect plan. Without a single dropped or lagging frame, A universe that whispers our own name." He turns back to his work, a single, massive dent In a water-damaged, sandy monument. An RTX 3090, its silicon heart, No more a relic, but a creative start. He'd found a broken capacitor, a tiny puff, And replaced it with a barnacle-made stuff. A conductive calcium, a secret of his own, A Reset Run bake off Done Done WINNER DeepSeek-V4-Flash 1.81x
- Camera
- Static, wide shot of a web application interface, centered.
- Motion
- Text streaming animation, numerical counters incrementing, progress bar filling, 'WINNER' badge reveal, 'X' multiplier reveal.
Motion design primitives
Synthesizable in Remotion · key components of the dual-terminal-bakeoff template.
DualTerminalRaceSplit
Two side-by-side terminal-like panes display text streaming, numerical counters incrementing, and progress bars filling simultaneously, highlighting a performance comparison.
+ Code construction recipe
Utilize `Sequence` and `AbsoluteFill` for layout. Implement text streaming with `spring` or `interpolate` on `text-content` or `opacity` for character reveals. Numerical counters use `interpolate` for smooth value transitions. Progress bars are `interpolate` on `width` property.
PerformanceMultiplierReveal
A large 'X' multiplier value animates into view at the bottom right, accompanied by a 'WINNER' badge, emphasizing the performance difference.
+ Code construction recipe
Use `spring` for the 'X' multiplier's scale and position, and `FadeIn` or `SlideIn` for the 'WINNER' badge. Ensure synchronized timing with the completion of the DualTerminalRaceSplit.
DynamicTextStream
Text content appears as if being typed or streamed in real-time, with varying speeds and occasional pauses, mimicking live generation.
+ Code construction recipe
Implement with `interpolate` on `substring` length or `opacity` for individual characters. Vary `duration` and `delay` within a `Sequence` to simulate natural typing rhythm. Can use `measureText` for accurate character-by-character timing.
Style DNA & aesthetic system
Visual aesthetic
Typography
Motion
Special effects
Pacing & rhythm
Conceptual story rhythm
- 1
The Setup
Purpose. Introduce the comparison framework and the initial problem statement.
Execution. Static shot of the 'Bakeoff' UI, showing the prompt and initial model selections.
- 2
The Race
Purpose. Demonstrate the real-time performance difference between the models.
Execution. Text streaming, numerical counters, and progress bars animate simultaneously in the DualTerminalRaceSplit.
- 3
The Verdict
Purpose. Clearly highlight the superior performance of the product.
Execution. The 'WINNER' badge and 'X' multiplier animate into view, solidifying the product's advantage.
- 4
The Proof
Purpose. Provide further evidence and context for the performance, showcasing different use cases.
Execution. Repeat of the 'Race' and 'Verdict' beats with different prompts and explanations, reinforcing the consistent superiority.
Remix in Animatiq Studio
Master remix prompt · agent-ready
Sample remix
Objective
A new cloud database service wants to showcase its query speed against a competitor.How the recipe adapts
The DualTerminalRaceSplit component would display two database query consoles, one for the new service and one for the competitor. DynamicTextStream would show SQL queries being typed and results streaming in. Numerical counters would display 'Query Time (ms)' and 'Records Processed/sec'. The PerformanceMultiplierReveal would highlight how many times faster the new service is for complex queries.Remix blueprint · dual-terminal-bakeoff
Scene durations (4 scenes, 30s)
Key Remotion components
Related AI Agents Product Launches
Explore all AI Agents launches →
To ensure that artificial general intelligence benefits all of humanity
Gopuff introduces Go, an AI shopping assistant built with SpaceXAI: say what you need and the order is placed.
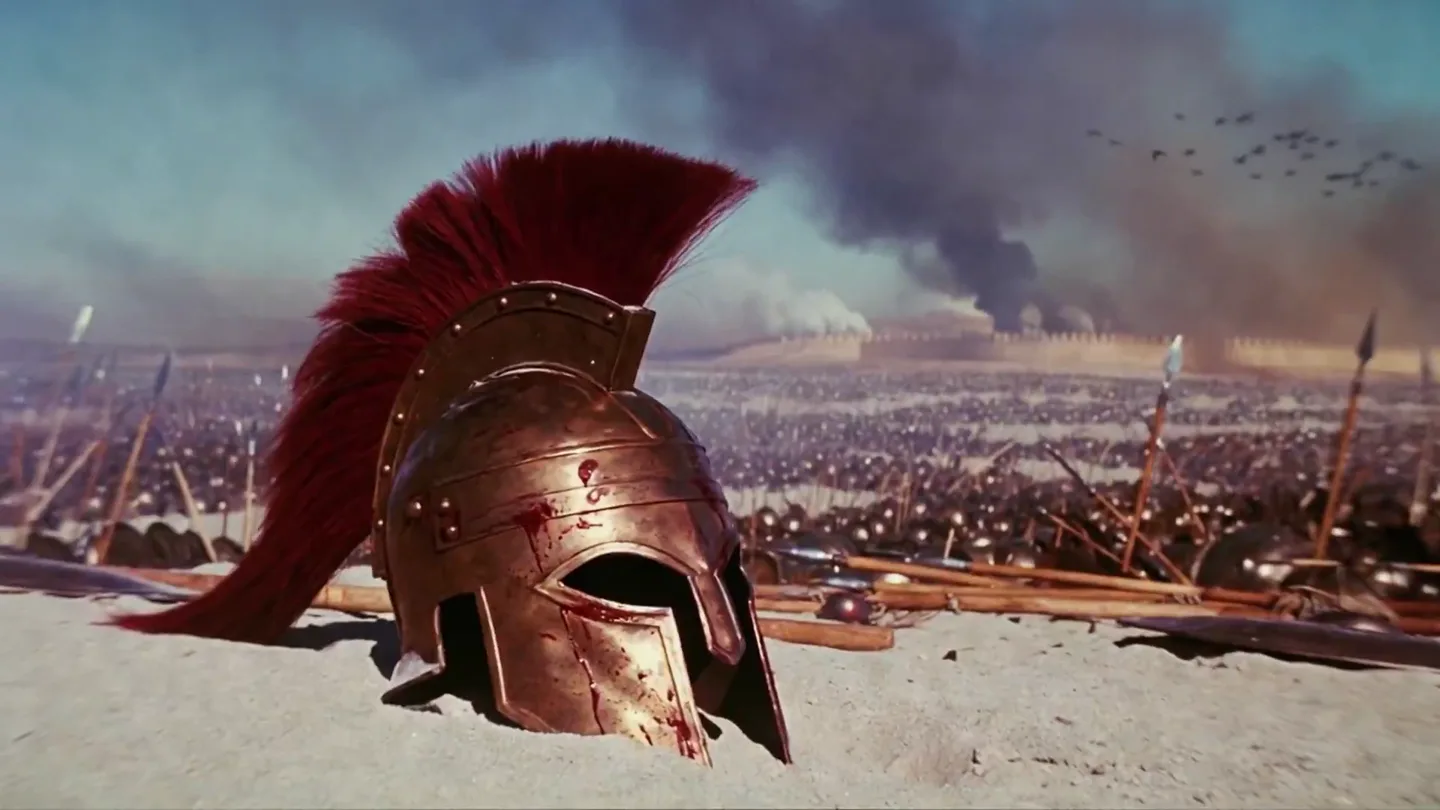
Iliad (Troy) trailer made by Grok Imagine 1.5, which was just released