Niels Rogge · Launch Video Breakdown: Hook, Pacing & Motion Design
Introducing a revival of PapersWithCode! As @ilyasut said, we're back to the "age of research". Hence, it's important to share research and build on each other's work. > find SOTA per domain, not j…
Scene-by-scene timeline & spoken transcript
The Hook
Introducing Papers With Code Revival
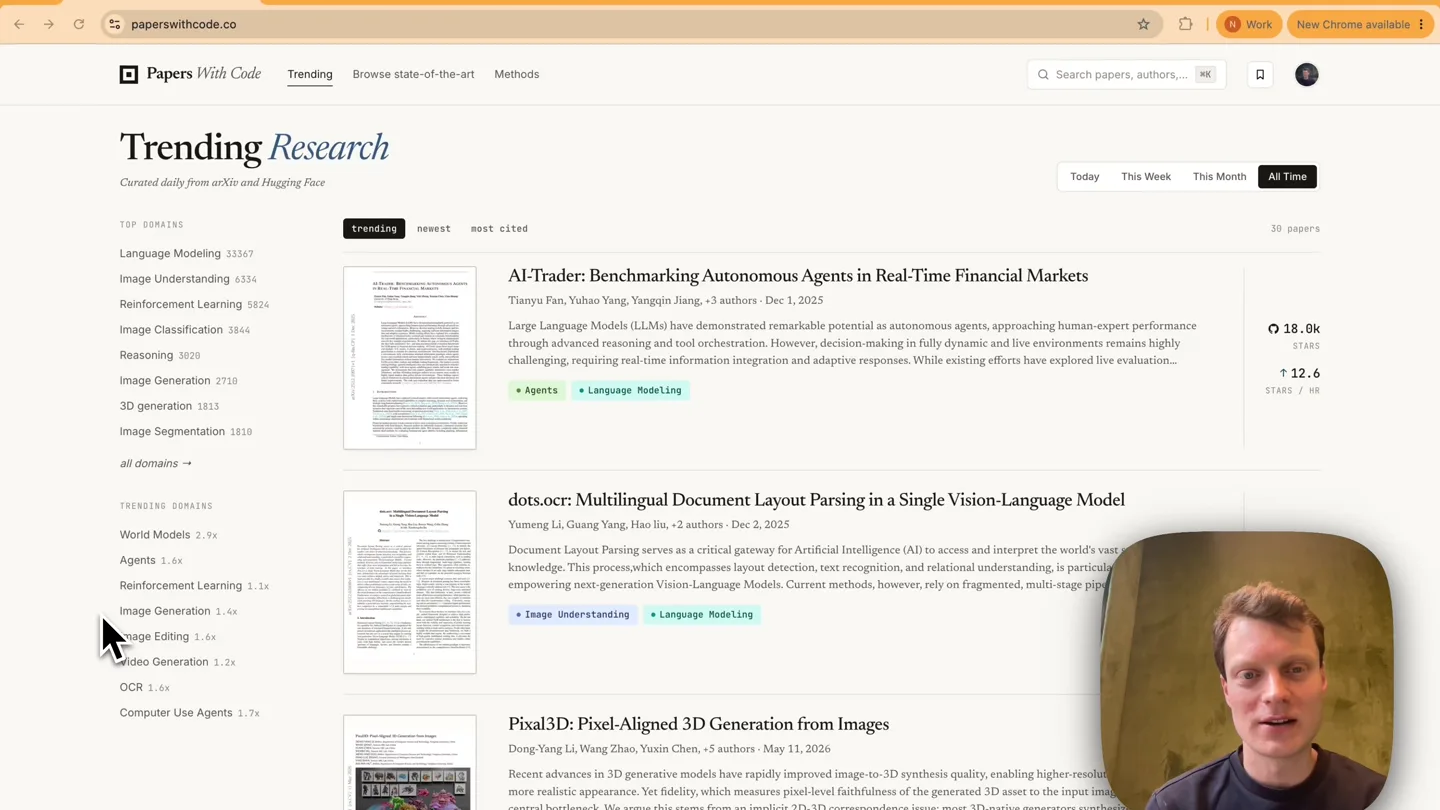
“Hey everyone, I'm Niels Rogge and I'm super excited to introduce you to Papers with Codes, a revival of the old Papers with Codes website. As Ilya Sutskever said, we're back to the age of research. Hence, it's important to share research and build on each other's work. And that's exactly what Papers with Codes tries to do. We use AI agents to parse and tag research papers with relevant categories and methods. Let me show you how it works.”
- On screen
- Papers With Code Trending Research Curated daily from arXiv and Hugging Face TOP DOMAINS Language Modeling 33367 Image Understanding 1834 Reinforcement Learning 5824 Image Classification 1644 Reasoning 3028 Image Generation 2738 3D generation 1815 Image Segmentation 1818 All domains GENERAL DOMAINS World Models 1.8k Agents 1.6k Reinforcement Learning 1.3k Image Generation 1.4k Image Editing 1.4k OCR 1.6k Computer Use Agents 1.7k AI-Trader: Benchmarking Autonomous Agents in Real-Time Financial Markets Agents Language Modeling dotsocr: Multilingual Document Layout Parsing in a Single Vision-Language Model Image Understanding Language Modeling Pixel3D: Pixel-Aligned 3D Generation from Images 3D generation 3D understanding 18.0k STARS 12.6 STARS / HR 8.7k STARS 2.4 STARS / HR 3.8k STARS 1.1 STARS / HR MiniCPM-o 4.5: Towards Real-Time Full-Duplex Omni-Modal Interaction arXiv:2684.27393 Submitted Apr 30, 2026 0 citations View PDF arXiv page Code 25.0k Project page edit Save ABSTRACT Recent progress in multimodal large language models (MLLMs) has brought Al capabilities from static offline data processing to real-time streaming interaction, yet they still remain far from human-level multimodal interaction. The key bottlenecks are no longer modality coverage or latency alone, but the interaction paradigm itself. First, perception and resp... + read full abstract TASKS edit Image Understanding Language Modeling Omni Models METHODS Gesini 2.5 GRPO Large language model (LLM) Qwen3 Whisper RESULTS 24 benchmarks edit IMAGE UNDERSTANDING 8 results BENCHMARK MODEL METRIC VALUE COMPARE MMMU MiniCPM-o 4.5-Instruct ACCURACY 67.6 MathVista MiniCPM-o 4.5-Instruct ACCURACY 88.1 AI2D MiniCPM-o 4.5-Instruct ACCURACY 87.6 MMStar MiniCPM-o 4.5-Instruct ACCURACY 73.1 DocVQA MiniCPM-o 4.5-Instruct ANLS 94.7 HallusionBench MiniCPM-o 4.5-Instruct ACCURACY 63.2 TextVQA MiniCPM-o 4.5-Instruct ACCURACY 83.8 3 tagged 5 used GRPO GROUP (Group Relative Policy Optimization) is a reinforcement learning (RL) algorithm that makes training Large Language Models (LLMs) more efficient by comparing multiple generated outputs to a group's average reward. Unlike traditional methods that require expensive "value function" models, GRPO uses a relative baseline from a group of sampled responses to determine how good each step is. This reduces computational and memory demands, making GRPO a key technology behind models like DeepSeekS, which are skilled at tasks requiring complex reasoning, such as solving math problems SOURCE DeepSeekMath: Pushing the Limits of Mathematical Reasoning in Open Language Models PAPERS USING 3,445 RELATED METHODS Large language model (LLM) Fine-tuning Transformer Softmax Layer Normalization Multi-head attention Dropout Adam newest most cited Self-Distilled Agentic Reinforcement Learning DeepSeekMath: Pushing the Limits of Mathematical Reasoning in Open Language Models arXiv:2402.03300 Submitted Feb 5, 2024 5,921 citations View PDF arXiv page Code 3.1k Add project page Save INTRODUCED GRPO This paper is the canonical source for this method. ABSTRACT Mathematical reasoning poses a significant challenge for language models due to its complex and unstructured nature. In this paper, we introduce DeepSeekMath, which continues pre-training DeepSeek-Coder-Base-v1.5 7B with 120B math-related tokens sourced from Common Crawl, together with natural language and code data. DeepSeekMath 7B has achieved an impressi... + read full abstract TASKS 1 tagged edit Language Modeling METHODS 25 used edit Adam BPE Direct Preference Optimization (DPO) Dropout GPT-4 GRPO Label smoothing Layer Normalization Multi-head attention PPO Pre-training Softmax Speculative decoding Transformer Tree of Thoughts RESULTS 0 benchmarks edit GitHub deepseek-ai/deepseek... 3.3k shibing624/medicalgpt 4.3k opensci-project/react 328 + show 2 more repos Hugging Face Models 100+ Datasets 20+ Spaces 10+ CITATION I tagged edit All Domains Browse research by area. Click any task to see trending work. General A broad category encompassing machine learning research and tasks that don't fit specifically into vision or language domains, including general ML methods, optimization, and cross-domain approaches. Agents 981 papers Coding Agents 233 papers Computer Use Agents 256 papers Embedding Models 867 papers Language Modeling 33,367 papers OCR 471 papers Omni Models 16 papers Reasoning 3,028 papers Reinforcement Learning 3,834 papers Robotics 544 papers World Models 98 papers Vision Research on enabling machines to interpret and understand still images, including image classification, generation, editing, segmentation, detection, depth, and 3D understanding. 3D generation 1,813 papers 3D understanding 968 papers Depth Estimation 649 papers Image Classification 3,844 papers Image Editing 698 papers Image Generation 2,738 papers LEADERBOARDS - CLICK ANY BENCHMARKS [10] 01 Terminal Bench 2.0 32 ENTRIES 02 SWE-Bench Verified 29 ENTRIES 03 LiveCodeBench 28 ENTRIES 04 SWE-Bench Multilingual 16 ENTRIES 05 SWE-Bench Pro 12 ENTRIES + show 5 more benchmarks TOP TRENDING - SORT BELOW PAPERS [233] trending newest most cited 12 Loaded in Coding Agents Agent READMEs: An Empirical Study of Context Files for Agentic Coding Coding Agents 21.4k STARS 1.2 STARS / HR METHODS 5 used edit GRPO Multi-latent attention (MLA) Post-training Qwen3 Speculative decoding RESULTS 22 benchmarks edit WORLD KNOWLEDGE 6 results BENCHMARK MODEL METRIC VALUE Humanity's Last Exam (HLE) GLM-5.1 (w/ tools) ACCURACY 52.3 Humanity's Last Exam (HLE) GLM-5 (w/ tools) ACCURACY 58.4 Humanity's Last Exam (HLE) GLM-5.1 ACCURACY 31.8 Humanity's Last Exam (HLE) GLM-5 ACCURACY 39.5 GPQA Diamond GLM-5.1 ACCURACY 86.2 GPQA Diamond GLM-5 ACCURACY 86.8 CODING AGENTS 6 results BENCHMARK MODEL METRIC VALUE Terminal Bench 2.0 GLM-5.1 ACCURACY 69.8 Terminal Bench 2.0 GLM-5.1 ACCURACY 63.5 Terminal Bench 2.0 GLM-5 ACCURACY 56.2 SWE-Bench Verified GLM-5 ACCURACY 77.8 SWE-Bench Multilingual GLM-5 ACCURACY 73.3 SWE-Bench Pro GLM-5.1 ACCURACY 58.4 AGENTS BENCHMARK MODEL METRIC VALUE Claw-Eval GLM-5.1 (General) ACCURACY 62.7 Claw-Eval GLM-5.1 (Multi Turn) ACCURACY 68.5 BrowseComp GLM-5.1 (w/ context manage) ACCURACY 79.3 SOTA progression 69.0 61.1 Accuracy 53.3 45.4 37.5 2025-08 2025-12 2026-02 2026-02 2026-02 Best result over time - hover a point to see the model - click to open the paper GLM-5.1 - Claude Code Accuracy: 69.0 GLM-5.1 from Vibe Coding to Agentic Engineering Trending Browse state-of-the-art Methods All Domains Browse research by area. Click any task to see trending work. General A broad category encompassing machine learning research and tasks that don't fit specifically into vision or language domains, including general ML methods, optimization, and cross-domain approaches. Agents 981 papers Coding Agents 233 papers Computer Use Agents 256 papers Embedding Models 867 papers Language Modeling 33,367 papers OCR 471 papers Omni Models 16 papers Reasoning 3,028 papers Reinforcement Learning 3,834 papers Robotics 544 papers World Models 98 papers Vision Research on enabling machines to interpret and understand still images, including image classification, generation, editing, segmentation, detection, depth, and 3D understanding. 3D generation 1,813 papers 3D understanding 968 papers Depth Estimation 649 papers Image Classification 3,844 papers Image Editing 698 papers Image Generation 2,738 papers Leaderboard RANK MODEL WRITER SCORE Microsoft harrier-oss-v1-27b 74.3 KaLM-Embedding-Gemma-3-12B-2511 72.3 Qwen3-Embedding-8B 70.6 llama-embed-nemotron-8b 69.5 Qwen3-Embedding-4B 69.5 harrier-oss-v1-0.0b 68.7 gemini-embedding-001 68.4 F2LLM-v2-14B 68.2 F2LLM-v2-48 67.0 Jina-embeddings-v0-text-small 67.0 Jina-embeddings-v0-base 67.0 harrier-oss-v1-270m 66.3 Microsoft Methods General 138 methods 299,902 papers Large language model (LLM) 23,723 papers Fine-tuning 9,439 papers Transformer 8,247 papers 2017 Softmax 7,166 papers 2014 Layer Normalization 6,695 papers Multi-head attention 8,835 papers Dropout 6,278 papers Adam 6,065 papers 2014 Pre-training 5,880 papers Chain-of-Thought (COT) 4,328 papers 2022 Label smoothing 3,864 papers 2015 Embedding 3,535 papers Direct Preference Optimization (DPO) 2,486 papers 2023 GRPO 3,445 papers RLHF 3,166 papers 2022 Convolution 3,277 papers Stable Diffusion 3,158 papers 2023 Diffusion Transformer (DiT) 2,898 papers 2022 LoRA 2,877 papers 2020 DeepSeek-R1 2,576 papers 2024 React 2,539 papers 2022 PPO 2,321 papers Scaling Laws 2,516 papers 2020 Classifier-free guidance 2,393 papers PEFT 2,477 papers 2021 Cosine Annealing 2,436 papers Qwen3 2,393 papers 2025 GPT-3 2,368 papers 2020 GPT-4 2,081 papers 2023 Gaussian splatting 2,393 papers Quantization Quantization is a process of converting data, signals, or parameters from a high-precision, continuous, or large set of values into a lower-precision, discrete, or smaller set of values. In machine learning, it's a technique used to reduce the computational cost, memory footprint, and energy consumption of Al models by converting high-precision data (like 32-bit floating-point numbers) into lower-precision formats (like 8-bit integers). While this can lead to a loss of accuracy, the goal is to maintain model performance while significantly improving inference speed and allowing models to run on more constrained hardware. PAPERS USING 1,316 RELATED METHODS Large language model (LLM) Fine-tuning Transformer Softmax Layer Normalization Trending Research Curated daily from arXiv and Hugging Face TOP DOMAINS Language Modeling 33367 Image Understanding 1834 Reinforcement Learning 5824 Image Classification 1644 Reasoning 3028 Image Generation 2738 3D generation 1815 Image Segmentation 1818 All domains GENERAL DOMAINS World Models 1.8k Agents 1.6k Reinforcement Learning 1.3k Image Generation 1.4k Image Editing 1.4k OCR 1.6k Computer Use Agents 1.7k AI-Trader: Benchmarking Autonomous Agents in Real-Time Financial Markets Agents Language Modeling dotsocr: Multilingual Document Layout Parsing in a Single Vision-Language Model Image Understanding Language Modeling Pixel3D: Pixel-Aligned 3D Generation from Images 3D generation 3D understanding 18.0k STARS 12.6 STARS / HR 8.7k STARS 2.4 STARS / HR 3.8k STARS 1.1 STARS / HR
- Camera
- Static wide shot of the presenter in the bottom right corner, overlaid on a screen recording of the website. The screen recording features mouse movements and clicks navigating the website.
- Motion
- Screen recording with presenter overlay, showcasing real-time UI interaction. Subtle cursor movements guide the viewer's attention.
Product Reveal
Navigating Research Papers and Benchmarks
“So here we are on the trending page. You can see the trending papers, you can filter by newest, most cited. You can also filter by domain. So for example, if you're interested in agents, you can click on agents and you'll see the trending papers for agents. You can also click on a paper to see more details. So for example, if you click on this paper, you'll see the abstract, the tasks, the methods, and the results. You can also click on the GitHub repository to see the code, or you can click on the arXiv page to see the full paper. You can also see the benchmarks for this paper, and you can compare them to other models.”
- On screen
- Papers With Code Trending Research Curated daily from arXiv and Hugging Face TOP DOMAINS Language Modeling 33367 Image Understanding 1834 Reinforcement Learning 5824 Image Classification 1644 Reasoning 3028 Image Generation 2738 3D generation 1815 Image Segmentation 1818 All domains GENERAL DOMAINS World Models 1.8k Agents 1.6k Reinforcement Learning 1.3k Image Generation 1.4k Image Editing 1.4k OCR 1.6k Computer Use Agents 1.7k AI-Trader: Benchmarking Autonomous Agents in Real-Time Financial Markets Agents Language Modeling dotsocr: Multilingual Document Layout Parsing in a Single Vision-Language Model Image Understanding Language Modeling Pixel3D: Pixel-Aligned 3D Generation from Images 3D generation 3D understanding 18.0k STARS 12.6 STARS / HR 8.7k STARS 2.4 STARS / HR 3.8k STARS 1.1 STARS / HR MiniCPM-o 4.5: Towards Real-Time Full-Duplex Omni-Modal Interaction arXiv:2684.27393 Submitted Apr 30, 2026 0 citations View PDF arXiv page Code 25.0k Project page edit Save ABSTRACT Recent progress in multimodal large language models (MLLMs) has brought Al capabilities from static offline data processing to real-time streaming interaction, yet they still remain far from human-level multimodal interaction. The key bottlenecks are no longer modality coverage or latency alone, but the interaction paradigm itself. First, perception and resp... + read full abstract TASKS edit Image Understanding Language Modeling Omni Models METHODS Gesini 2.5 GRPO Large language model (LLM) Qwen3 Whisper RESULTS 24 benchmarks edit IMAGE UNDERSTANDING 8 results BENCHMARK MODEL METRIC VALUE COMPARE MMMU MiniCPM-o 4.5-Instruct ACCURACY 67.6 MathVista MiniCPM-o 4.5-Instruct ACCURACY 88.1 AI2D MiniCPM-o 4.5-Instruct ACCURACY 87.6 MMStar MiniCPM-o 4.5-Instruct ACCURACY 73.1 DocVQA MiniCPM-o 4.5-Instruct ANLS 94.7 HallusionBench MiniCPM-o 4.5-Instruct ACCURACY 63.2 TextVQA MiniCPM-o 4.5-Instruct ACCURACY 83.8 3 tagged 5 used GRPO GROUP (Group Relative Policy Optimization) is a reinforcement learning (RL) algorithm that makes training Large Language Models (LLMs) more efficient by comparing multiple generated outputs to a group's average reward. Unlike traditional methods that require expensive "value function" models, GRPO uses a relative baseline from a group of sampled responses to determine how good each step is. This reduces computational and memory demands, making GRPO a key technology behind models like DeepSeekS, which are skilled at tasks requiring complex reasoning, such as solving math problems SOURCE DeepSeekMath: Pushing the Limits of Mathematical Reasoning in Open Language Models PAPERS USING 3,445 RELATED METHODS Large language model (LLM) Fine-tuning Transformer Softmax Layer Normalization Multi-head attention Dropout Adam newest most cited Self-Distilled Agentic Reinforcement Learning DeepSeekMath: Pushing the Limits of Mathematical Reasoning in Open Language Models arXiv:2402.03300 Submitted Feb 5, 2024 5,921 citations View PDF arXiv page Code 3.1k Add project page Save INTRODUCED GRPO This paper is the canonical source for this method. ABSTRACT Mathematical reasoning poses a significant challenge for language models due to its complex and unstructured nature. In this paper, we introduce DeepSeekMath, which continues pre-training DeepSeek-Coder-Base-v1.5 7B with 120B math-related tokens sourced from Common Crawl, together with natural language and code data. DeepSeekMath 7B has achieved an impressi... + read full abstract TASKS 1 tagged edit Language Modeling METHODS 25 used edit Adam BPE Direct Preference Optimization (DPO) Dropout GPT-4 GRPO Label smoothing Layer Normalization Multi-head attention PPO Pre-training Softmax Speculative decoding Transformer Tree of Thoughts RESULTS 0 benchmarks edit GitHub deepseek-ai/deepseek... 3.3k shibing624/medicalgpt 4.3k opensci-project/react 328 + show 2 more repos Hugging Face Models 100+ Datasets 20+ Spaces 10+ CITATION I tagged edit All Domains Browse research by area. Click any task to see trending work. General A broad category encompassing machine learning research and tasks that don't fit specifically into vision or language domains, including general ML methods, optimization, and cross-domain approaches. Agents 981 papers Coding Agents 233 papers Computer Use Agents 256 papers Embedding Models 867 papers Language Modeling 33,367 papers OCR 471 papers Omni Models 16 papers Reasoning 3,028 papers Reinforcement Learning 3,834 papers Robotics 544 papers World Models 98 papers Vision Research on enabling machines to interpret and understand still images, including image classification, generation, editing, segmentation, detection, depth, and 3D understanding. 3D generation 1,813 papers 3D understanding 968 papers Depth Estimation 649 papers Image Classification 3,844 papers Image Editing 698 papers Image Generation 2,738 papers LEADERBOARDS - CLICK ANY BENCHMARKS [10] 01 Terminal Bench 2.0 32 ENTRIES 02 SWE-Bench Verified 29 ENTRIES 03 LiveCodeBench 28 ENTRIES 04 SWE-Bench Multilingual 16 ENTRIES 05 SWE-Bench Pro 12 ENTRIES + show 5 more benchmarks TOP TRENDING - SORT BELOW PAPERS [233] trending newest most cited 12 Loaded in Coding Agents Agent READMEs: An Empirical Study of Context Files for Agentic Coding Coding Agents 21.4k STARS 1.2 STARS / HR METHODS 5 used edit GRPO Multi-latent attention (MLA) Post-training Qwen3 Speculative decoding RESULTS 22 benchmarks edit WORLD KNOWLEDGE 6 results BENCHMARK MODEL METRIC VALUE Humanity's Last Exam (HLE) GLM-5.1 (w/ tools) ACCURACY 52.3 Humanity's Last Exam (HLE) GLM-5 (w/ tools) ACCURACY 58.4 Humanity's Last Exam (HLE) GLM-5.1 ACCURACY 31.8 Humanity's Last Exam (HLE) GLM-5 ACCURACY 39.5 GPQA Diamond GLM-5.1 ACCURACY 86.2 GPQA Diamond GLM-5 ACCURACY 86.8 CODING AGENTS 6 results BENCHMARK MODEL METRIC VALUE Terminal Bench 2.0 GLM-5.1 ACCURACY 69.8 Terminal Bench 2.0 GLM-5.1 ACCURACY 63.5 Terminal Bench 2.0 GLM-5 ACCURACY 56.2 SWE-Bench Verified GLM-5 ACCURACY 77.8 SWE-Bench Multilingual GLM-5 ACCURACY 73.3 SWE-Bench Pro GLM-5.1 ACCURACY 58.4 AGENTS BENCHMARK MODEL METRIC VALUE Claw-Eval GLM-5.1 (General) ACCURACY 62.7 Claw-Eval GLM-5.1 (Multi Turn) ACCURACY 68.5 BrowseComp GLM-5.1 (w/ context manage) ACCURACY 79.3 SOTA progression 69.0 61.1 Accuracy 53.3 45.4 37.5 2025-08 2025-12 2026-02 2026-02 2026-02 Best result over time - hover a point to see the model - click to open the paper GLM-5.1 - Claude Code Accuracy: 69.0 GLM-5.1 from Vibe Coding to Agentic Engineering Trending Browse state-of-the-art Methods All Domains Browse research by area. Click any task to see trending work. General A broad category encompassing machine learning research and tasks that don't fit specifically into vision or language domains, including general ML methods, optimization, and cross-domain approaches. Agents 981 papers Coding Agents 233 papers Computer Use Agents 256 papers Embedding Models 867 papers Language Modeling 33,367 papers OCR 471 papers Omni Models 16 papers Reasoning 3,028 papers Reinforcement Learning 3,834 papers Robotics 544 papers World Models 98 papers Vision Research on enabling machines to interpret and understand still images, including image classification, generation, editing, segmentation, detection, depth, and 3D understanding. 3D generation 1,813 papers 3D understanding 968 papers Depth Estimation 649 papers Image Classification 3,844 papers Image Editing 698 papers Image Generation 2,738 papers Leaderboard RANK MODEL WRITER SCORE Microsoft harrier-oss-v1-27b 74.3 KaLM-Embedding-Gemma-3-12B-2511 72.3 Qwen3-Embedding-8B 70.6 llama-embed-nemotron-8b 69.5 Qwen3-Embedding-4B 69.5 harrier-oss-v1-0.0b 68.7 gemini-embedding-001 68.4 F2LLM-v2-14B 68.2 F2LLM-v2-48 67.0 Jina-embeddings-v0-text-small 67.0 Jina-embeddings-v0-base 67.0 harrier-oss-v1-270m 66.3 Microsoft Methods General 138 methods 299,902 papers Large language model (LLM) 23,723 papers Fine-tuning 9,439 papers Transformer 8,247 papers 2017 Softmax 7,166 papers 2014 Layer Normalization 6,695 papers Multi-head attention 8,835 papers Dropout 6,278 papers Adam 6,065 papers 2014 Pre-training 5,880 papers Chain-of-Thought (COT) 4,328 papers 2022 Label smoothing 3,864 papers 2015 Embedding 3,535 papers Direct Preference Optimization (DPO) 2,486 papers 2023 GRPO 3,445 papers RLHF 3,166 papers 2022 Convolution 3,277 papers Stable Diffusion 3,158 papers 2023 Diffusion Transformer (DiT) 2,898 papers 2022 LoRA 2,877 papers 2020 DeepSeek-R1 2,576 papers 2024 React 2,539 papers 2022 PPO 2,321 papers Scaling Laws 2,516 papers 2020 Classifier-free guidance 2,393 papers PEFT 2,477 papers 2021 Cosine Annealing 2,436 papers Qwen3 2,393 papers 2025 GPT-3 2,368 papers 2020 GPT-4 2,081 papers 2023 Gaussian splatting 2,393 papers Quantization Quantization is a process of converting data, signals, or parameters from a high-precision, continuous, or large set of values into a lower-precision, discrete, or smaller set of values. In machine learning, it's a technique used to reduce the computational cost, memory footprint, and energy consumption of Al models by converting high-precision data (like 32-bit floating-point numbers) into lower-precision formats (like 8-bit integers). While this can lead to a loss of accuracy, the goal is to maintain model performance while significantly improving inference speed and allowing models to run on more constrained hardware. PAPERS USING 1,316 RELATED METHODS Large language model (LLM) Fine-tuning Transformer Softmax Layer Normalization
- Camera
- Continues static wide shot with presenter overlay. The screen recording shows detailed navigation within the website, including clicking on specific papers, methods, and benchmarks.
- Motion
- Interactive screen recording with precise cursor movements, highlighting key UI elements and data points. Smooth scrolling and tab switching.
Feature Teaser
Exploring Domains, Benchmarks, and Methods
“You can also browse by state-of-the-art. So for example, if you're interested in embedding models, you can click on embedding models and you'll see the leaderboard for embedding models. You can also browse by methods. So for example, if you're interested in quantization, you can click on quantization and you'll see an explanation of quantization and the papers that use it. So this is just a quick overview of Papers with Codes. I'm super excited about this first draft, and I'm looking forward to adding more features in the future.”
- On screen
- Papers With Code Trending Research Curated daily from arXiv and Hugging Face TOP DOMAINS Language Modeling 33367 Image Understanding 1834 Reinforcement Learning 5824 Image Classification 1644 Reasoning 3028 Image Generation 2738 3D generation 1815 Image Segmentation 1818 All domains GENERAL DOMAINS World Models 1.8k Agents 1.6k Reinforcement Learning 1.3k Image Generation 1.4k Image Editing 1.4k OCR 1.6k Computer Use Agents 1.7k AI-Trader: Benchmarking Autonomous Agents in Real-Time Financial Markets Agents Language Modeling dotsocr: Multilingual Document Layout Parsing in a Single Vision-Language Model Image Understanding Language Modeling Pixel3D: Pixel-Aligned 3D Generation from Images 3D generation 3D understanding 18.0k STARS 12.6 STARS / HR 8.7k STARS 2.4 STARS / HR 3.8k STARS 1.1 STARS / HR MiniCPM-o 4.5: Towards Real-Time Full-Duplex Omni-Modal Interaction arXiv:2684.27393 Submitted Apr 30, 2026 0 citations View PDF arXiv page Code 25.0k Project page edit Save ABSTRACT Recent progress in multimodal large language models (MLLMs) has brought Al capabilities from static offline data processing to real-time streaming interaction, yet they still remain far from human-level multimodal interaction. The key bottlenecks are no longer modality coverage or latency alone, but the interaction paradigm itself. First, perception and resp... + read full abstract TASKS edit Image Understanding Language Modeling Omni Models METHODS Gesini 2.5 GRPO Large language model (LLM) Qwen3 Whisper RESULTS 24 benchmarks edit IMAGE UNDERSTANDING 8 results BENCHMARK MODEL METRIC VALUE COMPARE MMMU MiniCPM-o 4.5-Instruct ACCURACY 67.6 MathVista MiniCPM-o 4.5-Instruct ACCURACY 88.1 AI2D MiniCPM-o 4.5-Instruct ACCURACY 87.6 MMStar MiniCPM-o 4.5-Instruct ACCURACY 73.1 DocVQA MiniCPM-o 4.5-Instruct ANLS 94.7 HallusionBench MiniCPM-o 4.5-Instruct ACCURACY 63.2 TextVQA MiniCPM-o 4.5-Instruct ACCURACY 83.8 3 tagged 5 used GRPO GROUP (Group Relative Policy Optimization) is a reinforcement learning (RL) algorithm that makes training Large Language Models (LLMs) more efficient by comparing multiple generated outputs to a group's average reward. Unlike traditional methods that require expensive "value function" models, GRPO uses a relative baseline from a group of sampled responses to determine how good each step is. This reduces computational and memory demands, making GRPO a key technology behind models like DeepSeekS, which are skilled at tasks requiring complex reasoning, such as solving math problems SOURCE DeepSeekMath: Pushing the Limits of Mathematical Reasoning in Open Language Models PAPERS USING 3,445 RELATED METHODS Large language model (LLM) Fine-tuning Transformer Softmax Layer Normalization Multi-head attention Dropout Adam newest most cited Self-Distilled Agentic Reinforcement Learning DeepSeekMath: Pushing the Limits of Mathematical Reasoning in Open Language Models arXiv:2402.03300 Submitted Feb 5, 2024 5,921 citations View PDF arXiv page Code 3.1k Add project page Save INTRODUCED GRPO This paper is the canonical source for this method. ABSTRACT Mathematical reasoning poses a significant challenge for language models due to its complex and unstructured nature. In this paper, we introduce DeepSeekMath, which continues pre-training DeepSeek-Coder-Base-v1.5 7B with 120B math-related tokens sourced from Common Crawl, together with natural language and code data. DeepSeekMath 7B has achieved an impressi... + read full abstract TASKS 1 tagged edit Language Modeling METHODS 25 used edit Adam BPE Direct Preference Optimization (DPO) Dropout GPT-4 GRPO Label smoothing Layer Normalization Multi-head attention PPO Pre-training Softmax Speculative decoding Transformer Tree of Thoughts RESULTS 0 benchmarks edit GitHub deepseek-ai/deepseek... 3.3k shibing624/medicalgpt 4.3k opensci-project/react 328 + show 2 more repos Hugging Face Models 100+ Datasets 20+ Spaces 10+ CITATION I tagged edit All Domains Browse research by area. Click any task to see trending work. General A broad category encompassing machine learning research and tasks that don't fit specifically into vision or language domains, including general ML methods, optimization, and cross-domain approaches. Agents 981 papers Coding Agents 233 papers Computer Use Agents 256 papers Embedding Models 867 papers Language Modeling 33,367 papers OCR 471 papers Omni Models 16 papers Reasoning 3,028 papers Reinforcement Learning 3,834 papers Robotics 544 papers World Models 98 papers Vision Research on enabling machines to interpret and understand still images, including image classification, generation, editing, segmentation, detection, depth, and 3D understanding. 3D generation 1,813 papers 3D understanding 968 papers Depth Estimation 649 papers Image Classification 3,844 papers Image Editing 698 papers Image Generation 2,738 papers LEADERBOARDS - CLICK ANY BENCHMARKS [10] 01 Terminal Bench 2.0 32 ENTRIES 02 SWE-Bench Verified 29 ENTRIES 03 LiveCodeBench 28 ENTRIES 04 SWE-Bench Multilingual 16 ENTRIES 05 SWE-Bench Pro 12 ENTRIES + show 5 more benchmarks TOP TRENDING - SORT BELOW PAPERS [233] trending newest most cited 12 Loaded in Coding Agents Agent READMEs: An Empirical Study of Context Files for Agentic Coding Coding Agents 21.4k STARS 1.2 STARS / HR METHODS 5 used edit GRPO Multi-latent attention (MLA) Post-training Qwen3 Speculative decoding RESULTS 22 benchmarks edit WORLD KNOWLEDGE 6 results BENCHMARK MODEL METRIC VALUE Humanity's Last Exam (HLE) GLM-5.1 (w/ tools) ACCURACY 52.3 Humanity's Last Exam (HLE) GLM-5 (w/ tools) ACCURACY 58.4 Humanity's Last Exam (HLE) GLM-5.1 ACCURACY 31.8 Humanity's Last Exam (HLE) GLM-5 ACCURACY 39.5 GPQA Diamond GLM-5.1 ACCURACY 86.2 GPQA Diamond GLM-5 ACCURACY 86.8 CODING AGENTS 6 results BENCHMARK MODEL METRIC VALUE Terminal Bench 2.0 GLM-5.1 ACCURACY 69.8 Terminal Bench 2.0 GLM-5.1 ACCURACY 63.5 Terminal Bench 2.0 GLM-5 ACCURACY 56.2 SWE-Bench Verified GLM-5 ACCURACY 77.8 SWE-Bench Multilingual GLM-5 ACCURACY 73.3 SWE-Bench Pro GLM-5.1 ACCURACY 58.4 AGENTS BENCHMARK MODEL METRIC VALUE Claw-Eval GLM-5.1 (General) ACCURACY 62.7 Claw-Eval GLM-5.1 (Multi Turn) ACCURACY 68.5 BrowseComp GLM-5.1 (w/ context manage) ACCURACY 79.3 SOTA progression 69.0 61.1 Accuracy 53.3 45.4 37.5 2025-08 2025-12 2026-02 2026-02 2026-02 Best result over time - hover a point to see the model - click to open the paper GLM-5.1 - Claude Code Accuracy: 69.0 GLM-5.1 from Vibe Coding to Agentic Engineering Trending Browse state-of-the-art Methods All Domains Browse research by area. Click any task to see trending work. General A broad category encompassing machine learning research and tasks that don't fit specifically into vision or language domains, including general ML methods, optimization, and cross-domain approaches. Agents 981 papers Coding Agents 233 papers Computer Use Agents 256 papers Embedding Models 867 papers Language Modeling 33,367 papers OCR 471 papers Omni Models 16 papers Reasoning 3,028 papers Reinforcement Learning 3,834 papers Robotics 544 papers World Models 98 papers Vision Research on enabling machines to interpret and understand still images, including image classification, generation, editing, segmentation, detection, depth, and 3D understanding. 3D generation 1,813 papers 3D understanding 968 papers Depth Estimation 649 papers Image Classification 3,844 papers Image Editing 698 papers Image Generation 2,738 papers Leaderboard RANK MODEL WRITER SCORE Microsoft harrier-oss-v1-27b 74.3 KaLM-Embedding-Gemma-3-12B-2511 72.3 Qwen3-Embedding-8B 70.6 llama-embed-nemotron-8b 69.5 Qwen3-Embedding-4B 69.5 harrier-oss-v1-0.0b 68.7 gemini-embedding-001 68.4 F2LLM-v2-14B 68.2 F2LLM-v2-48 67.0 Jina-embeddings-v0-text-small 67.0 Jina-embeddings-v0-base 67.0 harrier-oss-v1-270m 66.3 Microsoft Methods General 138 methods 299,902 papers Large language model (LLM) 23,723 papers Fine-tuning 9,439 papers Transformer 8,247 papers 2017 Softmax 7,166 papers 2014 Layer Normalization 6,695 papers Multi-head attention 8,835 papers Dropout 6,278 papers Adam 6,065 papers 2014 Pre-training 5,880 papers Chain-of-Thought (COT) 4,328 papers 2022 Label smoothing 3,864 papers 2015 Embedding 3,535 papers Direct Preference Optimization (DPO) 2,486 papers 2023 GRPO 3,445 papers RLHF 3,166 papers 2022 Convolution 3,277 papers Stable Diffusion 3,158 papers 2023 Diffusion Transformer (DiT) 2,898 papers 2022 LoRA 2,877 papers 2020 DeepSeek-R1 2,576 papers 2024 React 2,539 papers 2022 PPO 2,321 papers Scaling Laws 2,516 papers 2020 Classifier-free guidance 2,393 papers PEFT 2,477 papers 2021 Cosine Annealing 2,436 papers Qwen3 2,393 papers 2025 GPT-3 2,368 papers 2020 GPT-4 2,081 papers 2023 Gaussian splatting 2,393 papers Quantization Quantization is a process of converting data, signals, or parameters from a high-precision, continuous, or large set of values into a lower-precision, discrete, or smaller set of values. In machine learning, it's a technique used to reduce the computational cost, memory footprint, and energy consumption of Al models by converting high-precision data (like 32-bit floating-point numbers) into lower-precision formats (like 8-bit integers). While this can lead to a loss of accuracy, the goal is to maintain model performance while significantly improving inference speed and allowing models to run on more constrained hardware. PAPERS USING 1,316 RELATED METHODS Large language model (LLM) Fine-tuning Transformer Softmax Layer Normalization
- Camera
- The static wide shot with presenter overlay continues. The screen recording demonstrates browsing different sections like 'Browse state-of-the-art' and 'Methods', showcasing leaderboards and method explanations.
- Motion
- Guided screen recording with deliberate mouse clicks and scrolling to reveal various features and content sections of the website.
Call to Action
Future Vision and Community Engagement
“So this is just a quick overview of Papers with Codes. I'm super excited about this first draft, and I'm looking forward to adding more features in the future. So stay tuned, and I hope you enjoy using Papers with Codes!”
- On screen
- (No on-screen text)
- Camera
- The presenter remains in the bottom right corner, while the screen recording continues to show the website, eventually returning to the trending page. The overall framing remains consistent.
- Motion
- Sustained screen recording with a final return to the initial landing page, reinforcing the product's core offering. The presenter's consistent presence maintains a personal connection.
Motion design primitives
Synthesizable in Remotion · key components of the founder-overlay-screencast-demo template.
PresenterOverlayScreenRecording
A live presenter's webcam feed is positioned in a fixed corner (bottom-right) of the screen, overlaid on a full-screen recording of a web application's UI. The presenter maintains eye contact and speaks directly to the camera while the UI is actively navigated.
+ Code construction recipe
Use a `Video` component for the screen recording as the base layer. Overlay a circular `Img` or `Video` component for the presenter's feed, positioned using `absolute` CSS positioning. Ensure the presenter's video has a transparent background or is masked to a circular shape. Synchronize presenter's speech with UI actions using `interpolate` for cursor movements and `Sequence` for scene changes.
GuidedCursorHighlight
A mouse cursor moves deliberately across the web application UI, highlighting clickable elements, scrolling through content, and opening new tabs or sections. The cursor's movement is smooth and purposeful, drawing attention to specific features as the presenter describes them.
+ Code construction recipe
Implement a custom SVG cursor component. Animate its `x` and `y` coordinates using `spring` or `interpolate` to follow a predefined path of UI interaction points. Use `delay` and `duration` to match the timing of the presenter's dialogue. Add subtle `scale` or `opacity` changes on hover/click states for interactive elements.
Style DNA & aesthetic system
Visual aesthetic
Typography
Motion
Special effects
Pacing & rhythm
Conceptual story rhythm
- 1
Personal Introduction & Problem Statement
Purpose. To establish credibility, introduce the product, and articulate the core problem it solves (sharing research in the 'age of research').
Execution. Presenter appears in a corner overlay, directly addressing the audience, while the website's initial landing page is shown in the background, setting the context.
- 2
Guided Product Tour
Purpose. To demonstrate the primary functionality of the website, showing how users can find and interact with research papers.
Execution. The presenter's cursor navigates through trending papers, clicks into a specific paper, and highlights key sections like abstract, tasks, methods, and results, including links to GitHub and arXiv.
- 3
Feature Deep Dive & Exploration
Purpose. To showcase advanced features like browsing by state-of-the-art, leaderboards, and detailed method explanations, emphasizing the depth of information available.
Execution. The cursor explores different navigation tabs ('Browse state-of-the-art', 'Methods'), revealing leaderboards for embedding models and detailed explanations of technical concepts like 'Quantization'.
- 4
Concluding Remarks & Future Vision
Purpose. To summarize the product's value, express enthusiasm for its potential, and hint at future developments.
Execution. The presenter reiterates the excitement for the product, maintaining the corner overlay while the website is shown, reinforcing the product as the central focus.
Remix in Animatiq Studio
Master remix prompt · agent-ready
Sample remix
Objective
Launch a new AI-powered code refactoring tool called 'RefactorFlow'.How the recipe adapts
The founder of RefactorFlow would appear in the bottom-right corner, explaining the tool's capabilities. The main screen would show a live demonstration of RefactorFlow's web interface, with the cursor navigating through codebases, selecting sections for refactoring, and showcasing the AI's suggestions and automated changes in real-time. The video would highlight features like 'Smart Suggestions', 'Automated Fixes', and 'Code Quality Metrics' with precise cursor movements and smooth scrolling through code files. The calm electronic music would underscore the focused, technical nature of the product.Remix blueprint · founder-overlay-screencast-demo
Scene durations (4 scenes, 181s)
Key Remotion components
Related AI Agents Product Launches
Explore all AI Agents launches →
To ensure that artificial general intelligence benefits all of humanity
Gopuff introduces Go, an AI shopping assistant built with SpaceXAI: say what you need and the order is placed.
Iliad (Troy) trailer made by Grok Imagine 1.5, which was just released